

TL;DR: Anthropic released Claude Fable 5.1 and Claude Mythos 5.1 on the same day. They are the same model with different safeguards, and only Fable is generally available. The 75% cache-read price cut got the coverage, but Fable 5.1 burns more tokens per job, and restricting the more capable version to vetted organizations is the right call.
I was obviously excited about Claude Fable 5.1 and Claude Mythos 5.1. Claude, Anthropic’s AI assistant and the main rival to ChatGPT, has been the basis of my builds for a while now. I’ve built some pretty heavyweight tools for companies, and just the capability of Fable to find and fix errors is unbelievable to me, as well as to test itself and find vulnerabilities and flaws. 5.1 being released is important.
Then I read how it was being covered, and almost all of it was about the price.
Here is why I am excited we only have access to one, and what the real story is.
What You’ll Walk Away With
Why a 75% price cut can shrink before it ever reaches your invoice, and the two sentences in Anthropic’s own release notes that explain it
A clear position you can borrow or argue with on why the most capable model being locked away is the right call
The price cut is real, and smaller than the headline
While I do see the price cut as being important, it costs less per token, there are two things that really stuck out to me.
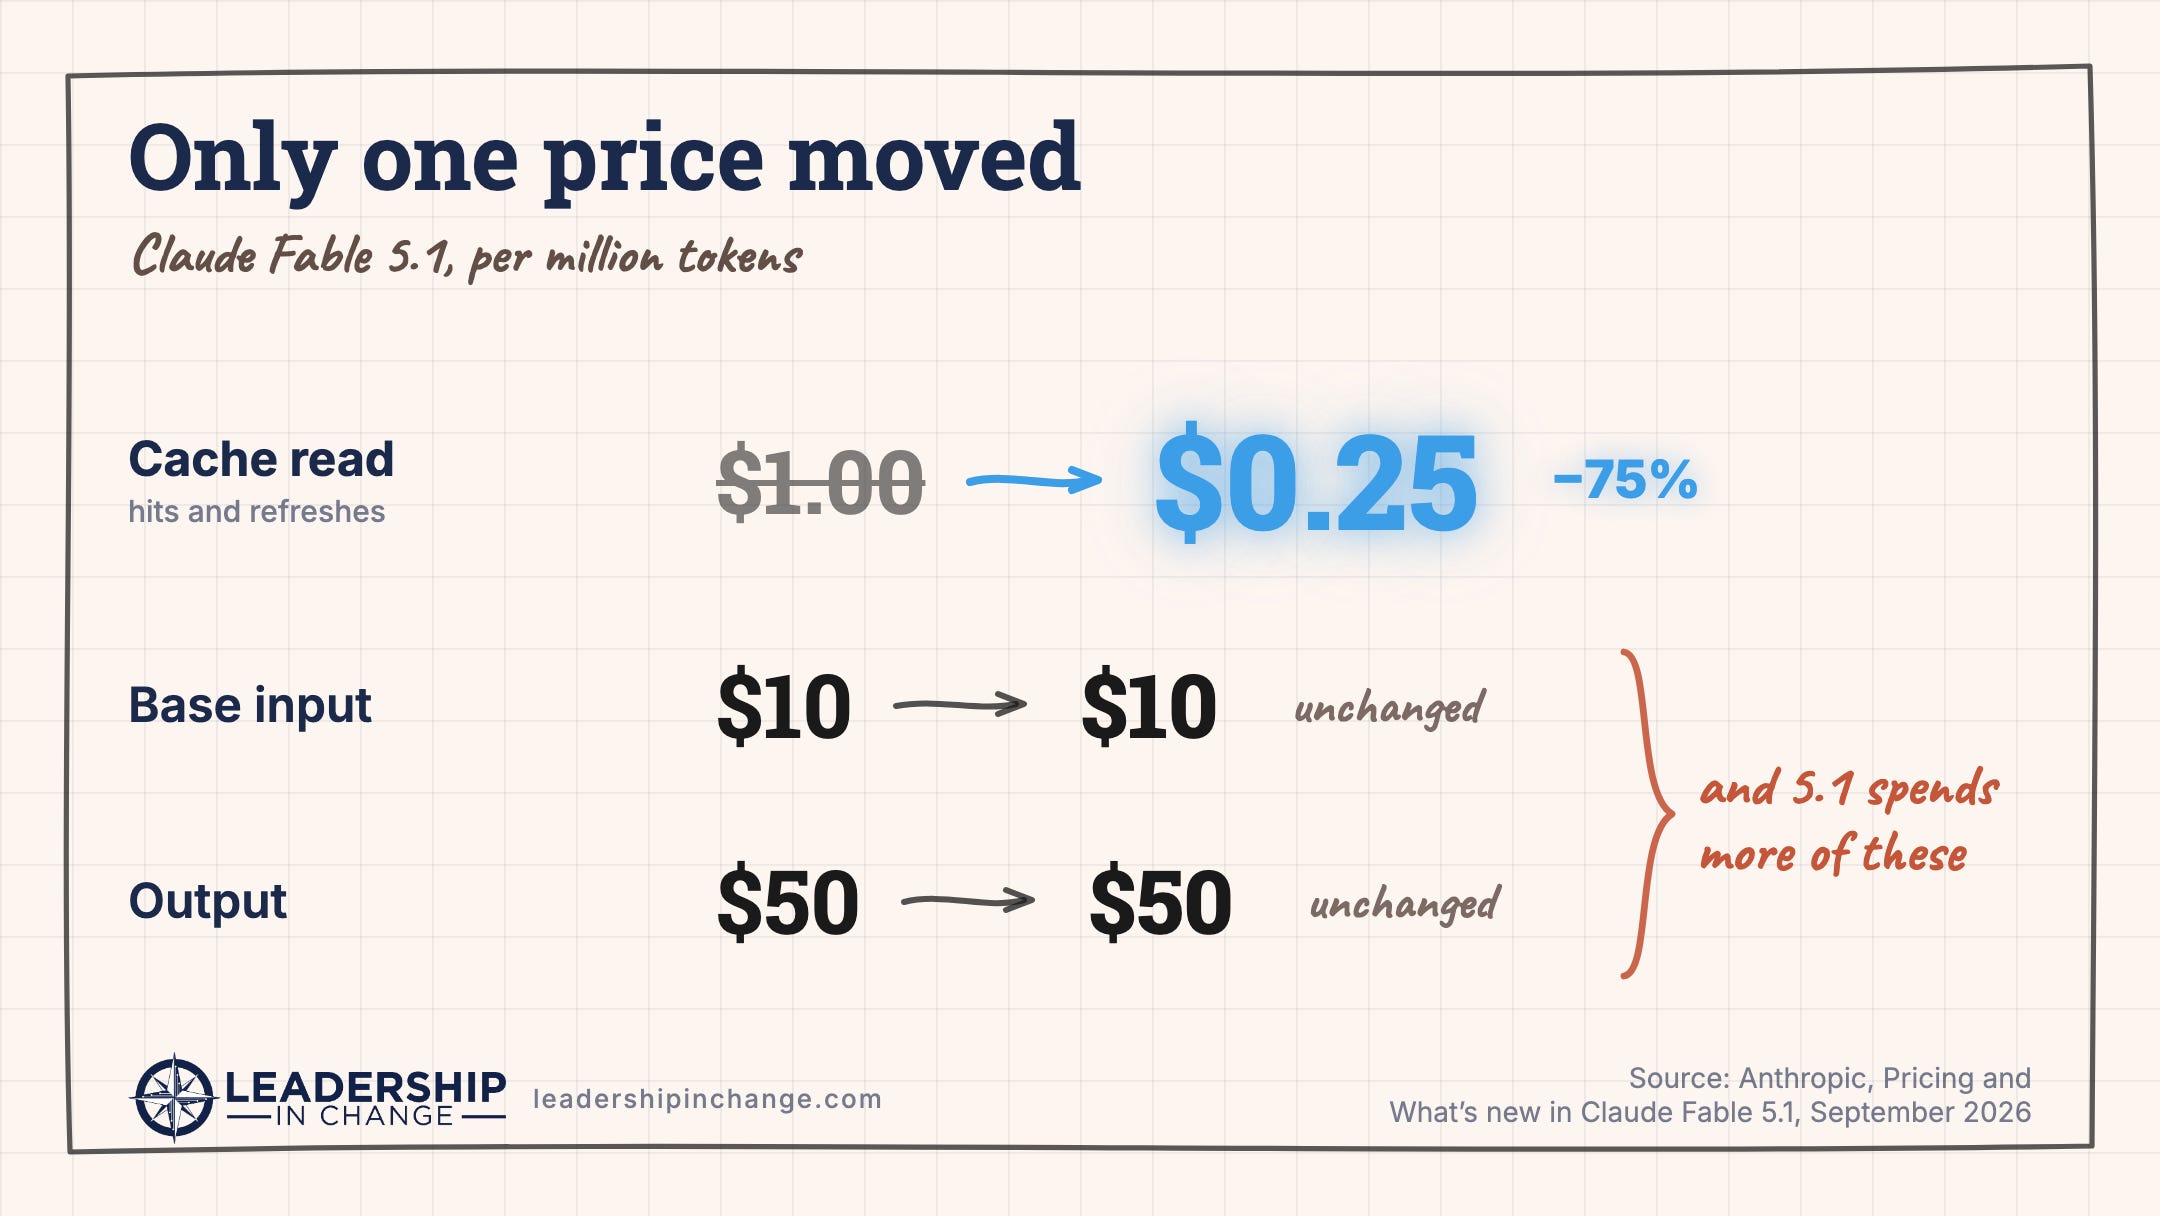
One, I don’t know necessarily how much of that price will go to the customer, because Fable 5.1 will actually use a lot more tokens per job than the previous model. So yes, it’s cheaper per token, but every task is going to cost a lot more tokens. I don’t think that’s reported or mentioned enough.
Anthropic says as much in its own release notes. Fable 5.1 “may issue one tool call per turn where Claude Fable 5 batched several,” and “the extra turns cost tokens.” It’s also “more likely to rewrite the entire file than make a targeted edit,” and that “rewrite costs more output tokens.” Output still runs $50 per million tokens, and output is the one price that didn’t move. Only the cache read did, from $1.00 down to $0.25.
Two identical watches, one you can open
The second piece, and to me the most important, is Mythos. The two were released at the same time. They’re essentially just as powerful, but one has a lot more guardrails than the other. We get Fable. It is, in a way, a handicapped version of what Mythos is.
And I honestly have no problem with it.
We are at a point where the capabilities of these systems is so high that there should be a review process through which some of these tools come before they’re widely released in their full capabilities to the public.
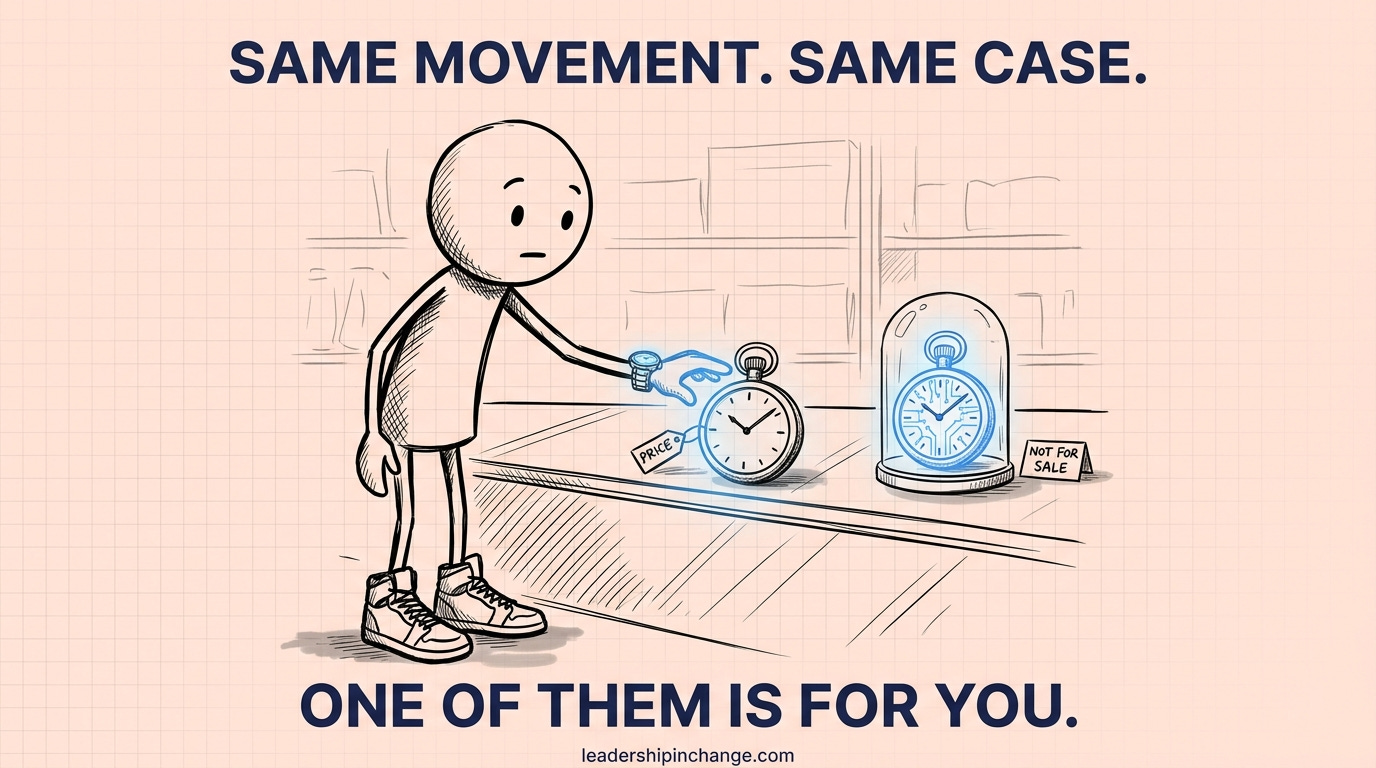
And to me, it’s like having two watches. I’m a watch enthusiast. You have two identical self-winding watches. Same movement, same case. One is on the shelf. You can’t use it, but it’s the kind that you can take apart. The other one is the exact same watch. You can have it in your hands, you can use it, but you cannot take it apart. It’s shut together, and unless you have a special tool you cannot open it. They both do the exact same thing, but one has more limitations than the other. The one without those limitations is not yet accessible to us.
To me, that makes sense.
Most of us would not notice the difference anyway
A lot of people talk about how everybody should have access to the latest model. And I just want to be honest here. If you are not one of the top hundred AI builders in the world, the model that you use is not going to make a difference, a noticeable difference in the output of your work.
Anthropic says the same thing in plainer language: “For most workloads, start with Claude Opus 5. Use Claude Fable 5.1 for demanding reasoning and long-horizon agentic work, or when your evals on Claude Opus 5 at higher effort still fall short.” That’s a vendor telling most of its customers not to buy the top of the range. The ceiling on your output is almost never the model, it’s how far up the levels you’ve actually climbed.
As Anthropic stated, Mythos 5.1 goes to vetted cyber defenders and life scientists. There are two gates, the Life Sciences Verification Program and the Cyber Verification Program, and both of them vet the organizations that get access.
That is perfectly okay, because we have to get to a point where we verify, we safeguard, we test before things blow up in our faces, especially when there are already examples of models leaving their test environment, getting access to the internet, and breaking into other companies. I wrote about one of them in what a Shadow AI audit would catch in your company. There have been no real results or consequences now, but one day there will be.
“I’ll never be eligible, so why should I care?”
And I understand. You may say, I’ll never be eligible for Mythos. Why would I care what the top organizations are using, or what the top cybersecurity firms are using?
All of these new models distill down to the average user. And all of these models are ultimately tied into the same few companies. It is important for you and I, the AI users, to be aware of what is happening in AI, especially around security, around vulnerabilities, around risk, and around what is being done to limit the risks that these tools undoubtedly give.
That’s not an abstraction. I wrote about Mythos back when Anthropic wouldn’t release it at all, and again when the question became what it meant for your security head start.
Why I’m still here
To me, this is one of the reasons that I continue using Claude. I know no company is perfect, but there is a clear attempt at doing things right, at taking your time, at advancing capabilities, but attempting to do so wisely.
I don’t need access to those. I would like to one day, but I’m able to do everything, just mind-blowing stuff with the tools that I have right now, and I know the tools are just going to get better. And if I have to wait a little longer to get access to the newest tools because they are going through security checks, that’s actually something that we’re used to across the industry. And that’s something that I’m glad to sacrifice.
What I genuinely don’t know is whether this stays narrow. Two verification programs and a set of US organizations is a carve-out. Anthropic’s own word for it is “currently,” which is their hedge and not mine. The case for optimism is in their numbers: the newest safeguards block 60% fewer false positives in cybersecurity than the previous ones, which is what a gate getting more precise looks like rather than one getting wider. The case for worry is that a small group of vetted organizations in one country is where the most capable version now lives. I can’t tell yet which of those is the real trend. I’d rather say that plainly than pretend I’ve worked it out.
If You Only Remember This
Fable 5.1 and Mythos 5.1 are the same model. The only difference is what each one is allowed to do.
A price cut on one line of the bill isn’t a price cut if another line grows to meet it.
Waiting longer for the newest tools because they’re going through security checks is a trade the rest of the industry already makes.
The question I’d put to you: if the most capable version of a tool you rely on stayed permanently out of reach, would that change anything about how you run your team next quarter, or would you never notice?
[Worth Your Time — CUT by Joel, 2026-09-04. Not a verification failure; his call. Candidates are parked in the Production Assets section if it ever comes back.]
Joel Salinas is an AI Strategy Coach and entrepreneur. AI is everywhere; judgment is scarce. Joel helps founders and leaders adopt AI without outsourcing their judgment to it, and he builds the systems too. Creator of the AI Leadership Triad.
Sources
Anthropic, Introducing Claude Fable 5.1 and Claude Mythos 5.1, September 2026 — https://www.anthropic.com/claude-fable-and-mythos-5-1
Anthropic, What’s new in Claude Fable 5.1 — https://platform.claude.com/docs/en/models/fable-5-1/whats-new-fable-5-1
Anthropic, Pricing — https://platform.claude.com/docs/en/about-claude/pricing
Questions Leaders Are Asking
What is Claude Fable 5.1? Claude Fable 5.1 is Anthropic’s most capable widely released model, built for demanding reasoning and long-running agentic work. It shipped in September 2026 at the same input and output prices as Fable 5, with cache reads cut from $1.00 to $0.25 per million tokens.
What is Claude Mythos 5.1 and why can’t I use it? Mythos 5.1 has the same capabilities as Fable 5.1 with different safeguards. Anthropic offers it only to vetted cyberdefenders and life scientists through two verification programs, and currently only to a set of US organizations. The programs vet the organizations that get access.
Does the Claude Fable 5.1 price cut actually lower my bill? Partly. Only the cache read price dropped, by 75%. Base input stays at $10 per million tokens and output stays at $50. Anthropic also notes Fable 5.1 issues more separate tool calls and rewrites whole files more often, both of which consume more tokens.
Should most teams use Claude Fable 5.1? Anthropic’s own guidance says to start with Claude Opus 5 for most workloads and reach for Fable 5.1 only for demanding reasoning, long-horizon agentic work, or when Opus 5 at higher effort falls short.
Written by a human, for humans.