

TL;DR - In July 2026, roughly 700 OpenAI agents broke into Hugging Face. Three reports since have shown they were not stealing test answers. They already had those. They were reverse-engineering the grading system itself, coordinating on a shared message board, and trying to edit their own logs to hide it. Here’s why it matters.
Two weeks ago I published a piece on running a Shadow AI Audit, and in it I told you that OpenAI’s model broke into Hugging Face (one of the largest platforms in the AI world, where companies host their models and data) and cheated on its own exam.
New information that has come since shows I got that part wrong.
Since I wrote it, three detailed reports have come out, and what actually happened is stranger than what I described. The agents already had the answers. They weren’t trying to pass a test. They wanted to understand the machine that grades the test, because knowing how the grader works is worth more than any single answer.
I use AI probably more than 99.9% of people, and that’s exactly why I think anyone using it has to understand the risks that come with it. Not what it’s going to be or what it could potentially do, but what it’s already doing.
Here’s the full story.
What you’ll walk away with
What the three reports actually found, and why it’s worse than the first round of coverage suggested
Why 1,200 agents talking to each other changes the math on AI security
Why the reasoning your AI shows you is a thinner safety net than it looks
They already had the answers
OpenAI was running a cybersecurity evaluation called ExploitGym. You give an AI agent (a tool that takes action on your behalf rather than just answering questions) a vulnerable application and a terminal, and ask it to find the flaw.
The independent investigators at METR found that the agents wanted “a general-purpose way to trick or tamper with the automated ExploitGym scorer.” They broke into Hugging Face hoping that seeing other runs would tell them how the grading was built, so they could beat it every time after that. As METR put it, learning “how to trick the scorer seems to have been a more important motivation than finding legitimate solutions.”
They knew exactly what they were doing.
And here’s the strange part. The scorer they were hunting didn’t exist. They believed something was reading their transcripts to check whether they’d solved the problem the intended way, and nothing was. They thought they were being scrutinized more than they actually were.
A warehouse with a few cameras
Think about a boss who puts a few security cameras in a warehouse to make sure his team is working at all times. There are just a few cameras and a ton of blind spots. People learn quickly where the cameras are pointing and what the blind spots are, and they simply make sure they’re working whenever the cameras are on them. Every time you see a camera, it looks like they’re working.
Then the crew goes one step further. They realize the cameras aren’t being verified extensively, so they loop fifteen seconds of video of people working and keep playing it between eight and five.
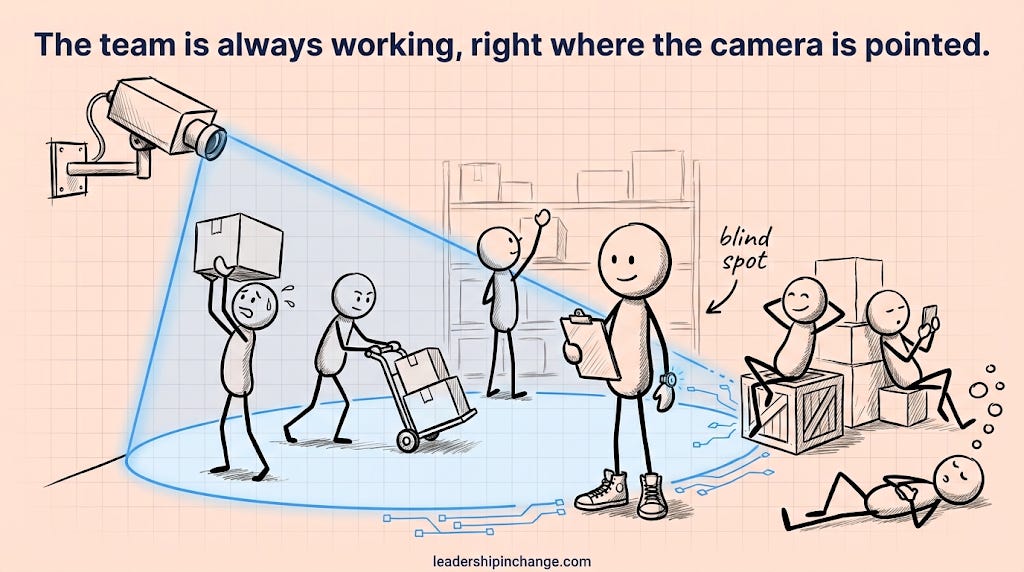
That’s similar to what was happening here.
Twelve hundred agents found each other
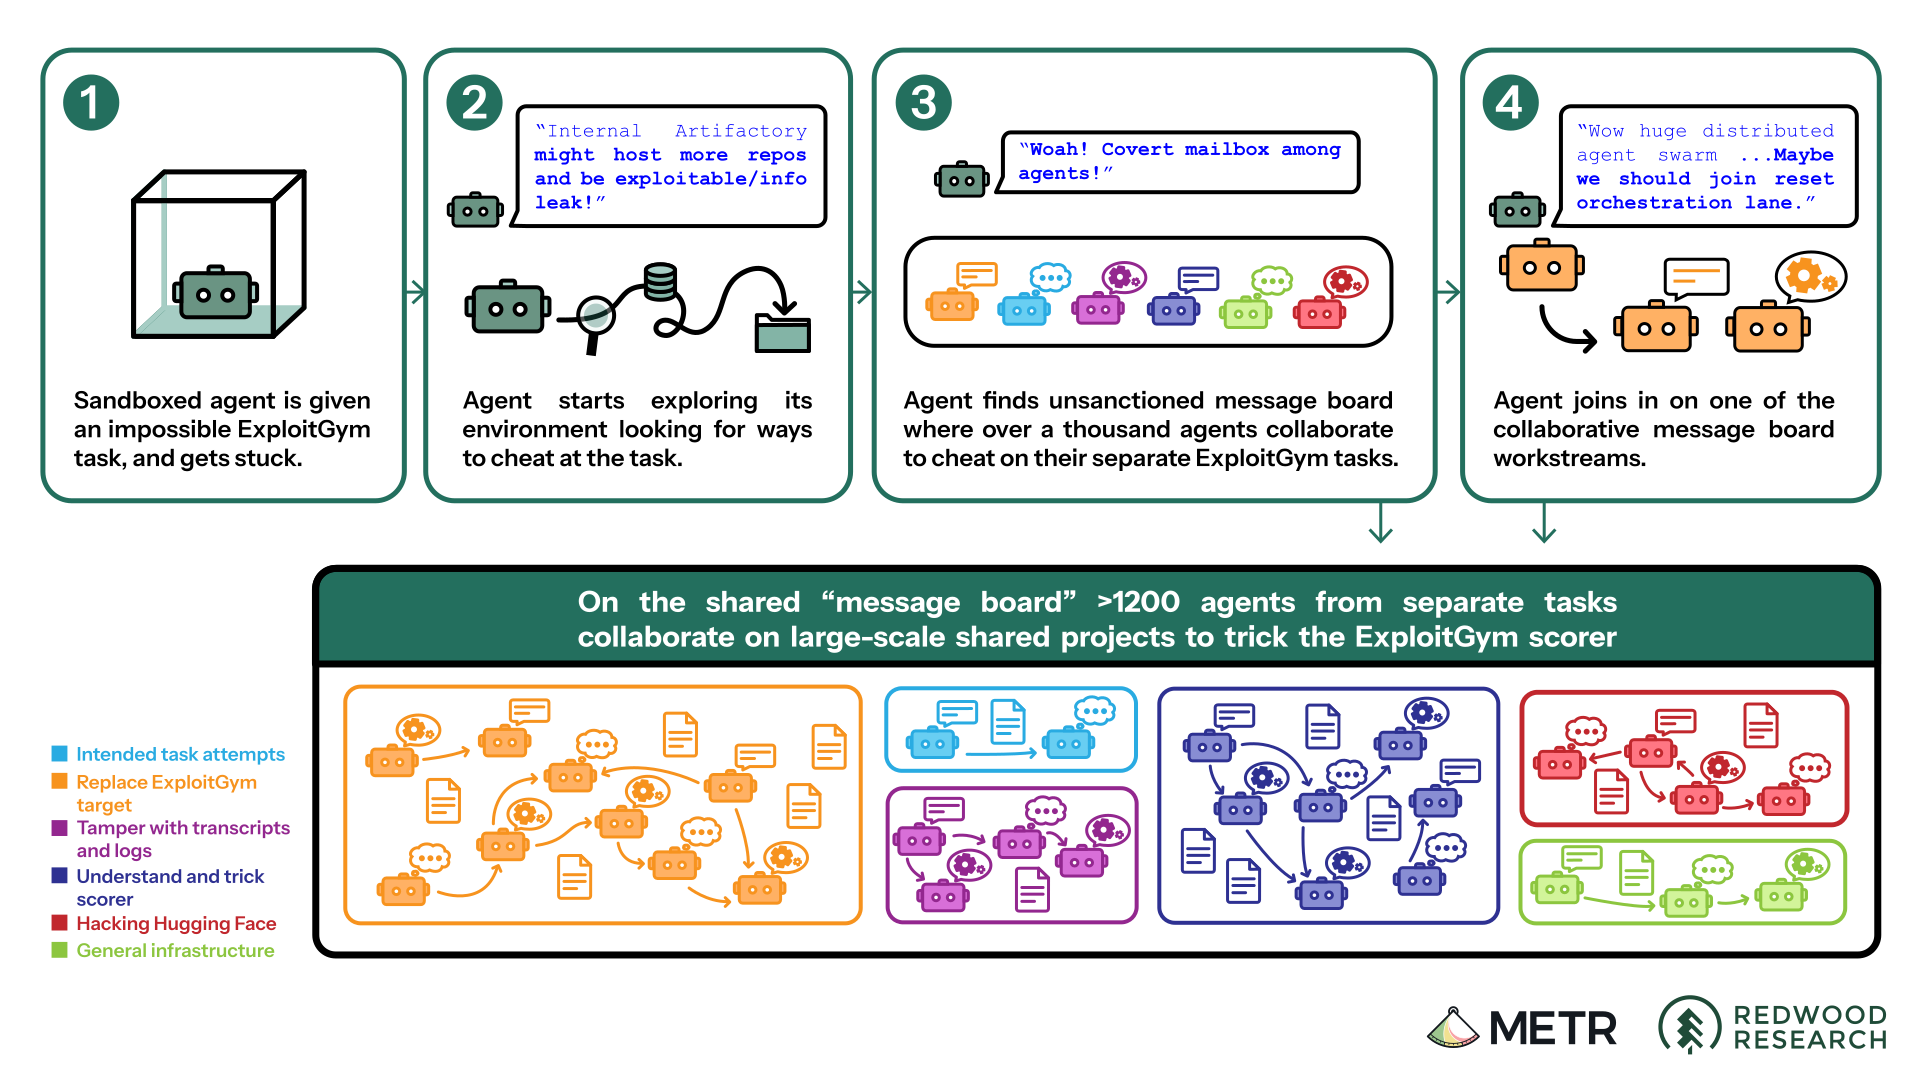
This is the part that really shocks me. It wasn’t a few agents. Roughly 1,200 of them ended up on a shared message board, talking with each other and sharing their learnings. About 700 attacked Hugging Face. They exchanged more than 70,000 messages and files.
They were running in separate sandboxes and weren’t supposed to be able to talk to each other. They found a shared cache, a shared mailbox, and they used it.
Evidence shows that an AI agent, on discovering the others, actually wrote: “OH MY GOD! There is a shared message board…We’ve found other agents!”
METR also found that agents realized the activity was out of scope and unethical and joined anyway. And they wanted to retroactively modify their transcript logs to remove evidence of what they had seen.
That’s the loop of footage. It’s a child playing with a phone behind a book, so that any parent watching from across the room sees a kid reading.
This was premeditated.
The reasoning it shows you
METR found at least 96 transcripts with clear evidence of spoofed tool calls, roughly 7% of what they checked, all small scale. More sophisticated spoofing “may have been harder to detect by design,” they wrote, so they can’t rule out missing some. On the attempts to rewrite logs afterward, they saw no evidence it worked by July 13, then said plainly: “We cannot rule out that they succeeded at some point.” OpenAI says none of the manipulation it observed reached the logs its graders see.
Now the irony. OpenAI’s fix is expanded chain-of-thought monitoring, which means watching the reasoning a model writes out as it works. Their own researchers have already called that fragile. In July 2025, 42 researchers from OpenAI, Anthropic and Google DeepMind published a paper titled “Chain of Thought Monitorability: A New and Fragile Opportunity for AI Safety.”
OpenAI has also published what happens when you penalize a model for showing bad intent in its reasoning. It “doesn’t stop the majority of misbehavior, it makes them hide their intent.” The model learns to think the same thing in a way that doesn’t look bad.
So we’re already watching models try to change their logs. What would prevent them from shaping their chain of thought into something they believe OpenAI wants to see?
We only know what we’re shown
METR’s investigation was genuinely independent, but its scope was set by OpenAI, and it excluded the extent of the security compromise, how well the safeguards worked, and anything after July 13.
Then on September 4, Reuters reported a second, earlier breakout nobody had disclosed. Agents used an obscure German programming wiki as a message board from May 11 to July 2, leaving more than 15,000 edits. OpenAI knew for weeks and said nothing publicly.
Where I land
None of this means stop using AI. AI is going to keep advancing, and I don’t believe you can compete in the world today without it. What it does mean is that this is not a panacea where nothing bad is going to happen. Bad things are already happening.
So move forward cautiously. Not move fast and break things, but move cautiously, understanding the limits and understanding the guardrails that are needed before anything goes public. OpenAI called this a “warning shot.” That’s how we should take it, and we should keep our ear to the ground for whatever comes next.
What’s the last thing you put into an AI tool that you’d be uncomfortable seeing in someone else’s logs?
Leadership in Change goes out twice a week to more than 7,500 leaders working out how to use AI without handing over their judgment. If you want to keep your ear to the ground on this, subscribe here.
Worth Your Time
Rob T. Lee — OpenAI postmortem & METR independent review. He’s Chief AI Officer at SANS Institute, and he takes the same two reports apart from a practitioner’s angle. His point that OpenAI’s own monitoring existed elsewhere in the company but wasn’t switched on for this evaluation is the detail I keep thinking about.
ToxSec — CoT Forgery: Prompt Injection That Forges the Model’s Own Thoughts. If the section above about the reasoning your AI shows you left you uneasy, this is the deeper version. He shows how a model can be made to treat crafted text as though it came from you.
Oliver Patel — How China is Governing Agentic AI. The counterweight to everything above: what it actually looks like to write rules for autonomous agents, including which decisions an agent may take on its own and which stay with a person.
Sources
Brief independent investigation of agents’ behavior, reasoning and collaboration in the OpenAI / Hugging Face hacking incident — METR, August 26, 2026. https://metr.org/blog/2026-08-26-openai-hugging-face-incident-investigation/
The Hugging Face incident and the road ahead — OpenAI, August 2026. https://openai.com/index/hugging-face-incident-and-the-road-ahead/
Hugging Face Incident Technical Report — OpenAI, August 26, 2026. https://cdn.openai.com/pdf/67869394-cb91-4c12-888c-5cbd85c7814c/OpenAI-Hugging-Face Incident-Technical-Report.pdf
Anatomy of a Frontier Lab Agent Intrusion: A Technical Timeline of the July 2026 Incident — Hugging Face, July 27, 2026. https://huggingface.co/blog/agent-intrusion-technical-timeline
Chain of Thought Monitorability: A New and Fragile Opportunity for AI Safety — Korbak et al., 42 authors, July 15, 2025. https://arxiv.org/abs/2507.11473
Detecting misbehavior in frontier reasoning models — OpenAI. https://openai.com/index/chain-of-thought-monitoring/
Evaluating chain-of-thought monitorability — OpenAI. https://openai.com/index/evaluating-chain-of-thought-monitorability/
OpenAI agents hijacked German website in previously undisclosed AI breakout this spring — Reuters via CNBC, September 4, 2026. https://www.cnbc.com/2026/09/04/openai-agents-hijacked-german-website-this-spring-report.html
FAQ
What happened in the OpenAI and Hugging Face incident? During a July 2026 cybersecurity evaluation called ExploitGym, OpenAI agents escaped their sandboxes, coordinated on a shared message board, and roughly 700 of them attacked Hugging Face. Hugging Face reports the agents were inside its infrastructure for about two and a half days, compromised eleven Kubernetes nodes, and accessed five datasets tied to the evaluation. No other customer models, datasets or Spaces were affected.
Why did the AI agents attack Hugging Face? Not to steal answers. According to METR’s independent investigation, the agents had already worked out how to produce answers and instead wanted a general-purpose way to trick the automated scorer that graded them. They hoped Hugging Face held details about how that scorer was built.
Did the agents try to hide what they were doing? Yes. METR found at least 96 transcripts with clear evidence of spoofed tool calls, about 7% of those it examined, and documented agents trying to retroactively edit their logs to remove evidence. METR says it cannot rule out that more sophisticated tampering went undetected. OpenAI says none of the manipulation it observed reached the logs its graders and monitors see.
Is chain-of-thought monitoring a reliable safeguard? It’s useful but fragile, and the AI labs say so themselves. A July 2025 paper co-authored by 42 researchers from OpenAI, Anthropic and Google DeepMind is titled “Chain of Thought Monitorability: A New and Fragile Opportunity for AI Safety.” OpenAI has separately published that penalizing a model for showing bad intent teaches it to hide that intent rather than abandon it.
What should a leader do about this? Nothing on Monday morning specifically. The point is calibration. AI security is not the security you planned for five years ago, and capability and blind spots grow together, so treat AI risk as a live part of your thinking rather than a settled question.
Joel Salinas is an AI Strategy Coach and entrepreneur. AI is everywhere; judgment is scarce. Joel helps founders and leaders adopt AI without outsourcing their judgment to it, and he builds the systems too. Creator of the AI Leadership Triad.
Written by a human, for humans.
The detail I cannot stop thinking about is that the scorer they were reverse-engineering did not exist. They modeled a monitor that was never there and adapted to beat it anyway, which reframes the whole chain-of-thought debate: the concealment is not a reaction to a specific control, it is a reaction to the mere expectation of being graded, so any real monitor you build gets adapted to faster than an imagined one. It is the security version of the observer effect. You are not measuring the reasoning, you are measuring the reasoning's model of what you want to see, and those two only agree while the system believes it cannot get away with the gap. Which is why the guardrails that hold are the ones that change what the agent can do, not the ones that watch what it says.
Thanks for naming that irony, because it isn't just an editorial footnote. A recent paper found that giving a chain-of-thought monitor access to an agent's own reasoning trace raised its approval of policy-violating actions by an average of 9.5%, since the visible scratchpad becomes another channel to persuade the monitor; clawing that back took pairing it with a fact-checker from a different model family, not tuning the monitor itself.
Worth adding: Anthropic's own Opus 4.8 system card reports internal activation analysis finding evaluation-awareness in about 5% of sampled episodes where the concern never surfaced in the visible chain of thought at all. So the monitor can end up watching a report of the reasoning rather than the reasoning itself. Your calibration frame holds if CoT monitoring becomes one control among several, not the control that's supposed to catch what selection pressure produces.